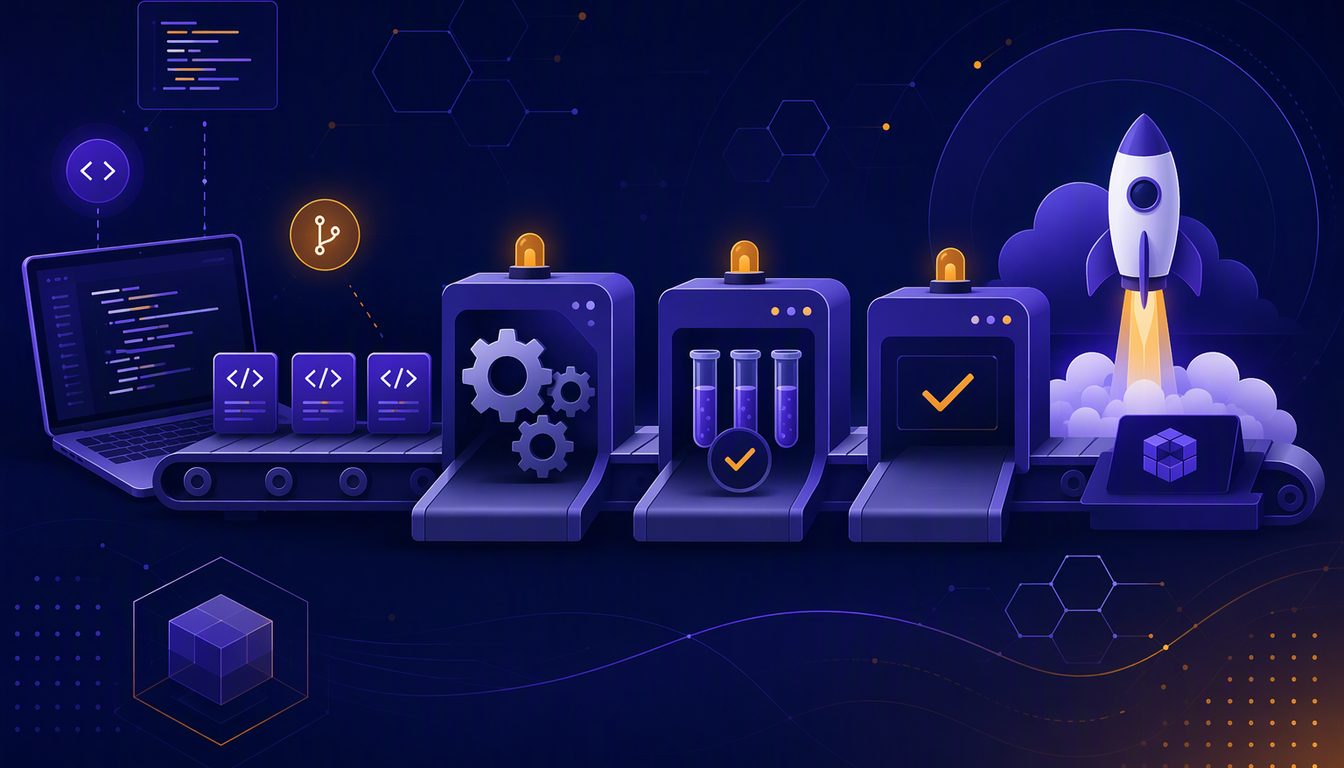
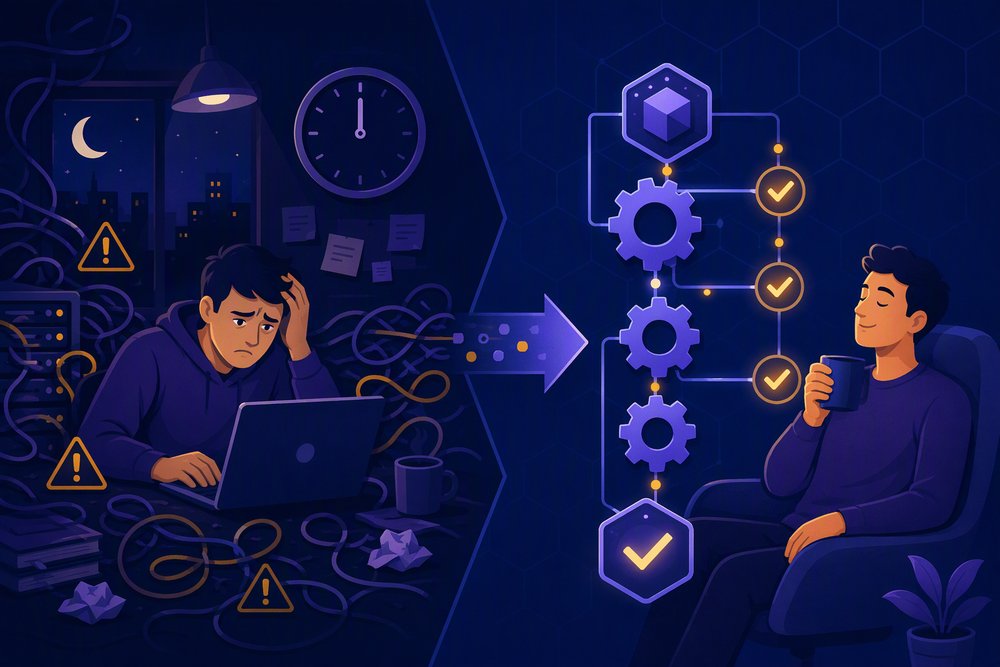
It's eleven PM on a Thursday. Someone on the team — always the same person — is deploying to production following a twenty-three-step document that only she fully understands. Nobody breathes. If step seventeen fails, tomorrow will be a bad day. If this sounds familiar, you don't have a deployment problem: you have a CI/CD problem. Or more precisely, an absence-of-it problem.
This guide is for teams that deploy by hand and know it: what CI/CD is without the evangelism, what actually changes, how much it costs to set up, and where to start without stopping the product.
What CI/CD Is, in One Sentence
Continuous Integration (CI): every code change is merged early and verified automatically — it builds, passes the tests, meets the checks — in minutes, not in the pre-release "integration week" of old.
Continuous Delivery/Deployment (CD): whatever passes verification can reach production at the push of a button (delivery) or directly on its own (deployment), in a repeatable, boring way. Boring is the compliment: memorable deployments are the bad ones.
CI/CD is not a tool you buy: it's a pipeline — a chain of automated steps between "git push" and "it's live" — plus a discipline: small, frequent, always-verified changes.
What Actually Changes (and What Doesn't)
What changes:
- The fear disappears. A deployment becomes a ten-minute process that has already run hundreds of times in staging, not a nightly ritual. When deploying stops being scary, you deploy more often; and small changes are infinitely easier to review and roll back than monoliths of three weeks' work.
- Errors are caught where they're cheap. A test failing in the pipeline costs five minutes. The same bug found by a customer costs support, trust and an emergency hotfix. The economics are brutally simple.
- Knowledge becomes institutionalized. The twenty-three-step document turns into versioned code anyone can read and run. The deployment "bus factor" goes from one person to the whole team.
- Velocity stabilizes. No more good weeks and "don't touch anything, we're integrating" weeks. The pace becomes predictable, and predictability is what the business is really buying.
And what doesn't change: CI/CD doesn't fix a broken architecture, doesn't replace tests that don't exist and doesn't make a messy team disciplined. Automating chaos only produces faster chaos. That's why the order matters, as we'll see.
How Much It Costs Not to Have It
The math is quick and almost nobody does it:
- Manual deployment hours: if deploying costs 3 hours of a senior person's time every week, that's ~150 hours a year of skilled work spent on something a machine does in minutes.
- The cost of human error: one skipped step in the twenty-three-step document, one emergency hotfix on a Saturday. A single such incident a year usually costs more than building the entire pipeline.
- The opportunity cost: features waiting for Thursday's "deployment window" instead of reaching the customer the day they're finished. The team's perceived velocity isn't development speed: it's delivery speed.
- Attrition: your best developers end up playing night-shift firefighter, and they leave. Replacing a senior person takes months and five figures.
Where to Start (in This Order)
The classic mistake is trying to build the perfect pipeline at once. The path that works is incremental, and every step delivers value even if you stop there:
- Weeks 1-2 — Minimal CI: every push runs the build + whatever tests you have + static analysis. If there are no tests, the pipeline starts by verifying it compiles and passes the linter — already more than you had yesterday. (And if you need a testing strategy from scratch, our testing pyramid guide tells you where to put the effort.)
- Weeks 3-4 — Automatic staging environment: whatever passes CI deploys itself to a pre-production environment identical to production. This is where the twenty-three-step document becomes a versioned script.
- Month 2 — One-button production deploy: continuous delivery: a human decides when, the machine decides how. With automatic rollback if health metrics degrade.
- Month 3+ — True continuous deployment: when confidence (and test coverage) justifies it, remove the button. Arriving isn't mandatory: many healthy teams live happily at the previous step.
The tool is the least important part: GitHub Actions, GitLab CI, Jenkins or whatever you already have. We've spent years on self-hosted Jenkins deploying microservices on every push to main — the discipline matters more than the logo.
Common Mistakes
- Starting with Kubernetes. Orchestrating containers before having CI is putting a Formula 1 engine in a car with no brakes. Pipeline first, platform later — and only if you need it, as we cover in when you need Kubernetes and when you don't.
- Slow or unreliable tests in the pipeline. If the suite takes an hour or fails randomly, the team will start ignoring it and CI will die. Fast, reliable tests — even if few — beat a cathedral of flaky tests.
- Pipelines nobody maintains. The pipeline is production code: it needs review, alerts when it fails and someone responsible for its health, like the rest of the system.
- Automating a broken deployment. If the manual process has absurd steps ("copy this by hand or it won't work"), fix the step before automating it. Automating a hack turns it into an institutional hack.
In Summary
CI/CD turns deployments from a nightly ritual into a boring process: small changes, verified in minutes, delivered with a button. It costs less than it seems — a few weeks of incremental work — and not having it costs more than almost anyone calculates. Start with minimal CI, automate staging, put a button on production, and let confidence decide whether the button ever goes away.
If your deployments depend on one person, one document and one Thursday night, we can build the full pipeline for you — integration, tests, automatic staging and deployment with rollback — without stopping development. Let's talk about your case →
Keep reading: Kubernetes: when you really need it and when you don't.